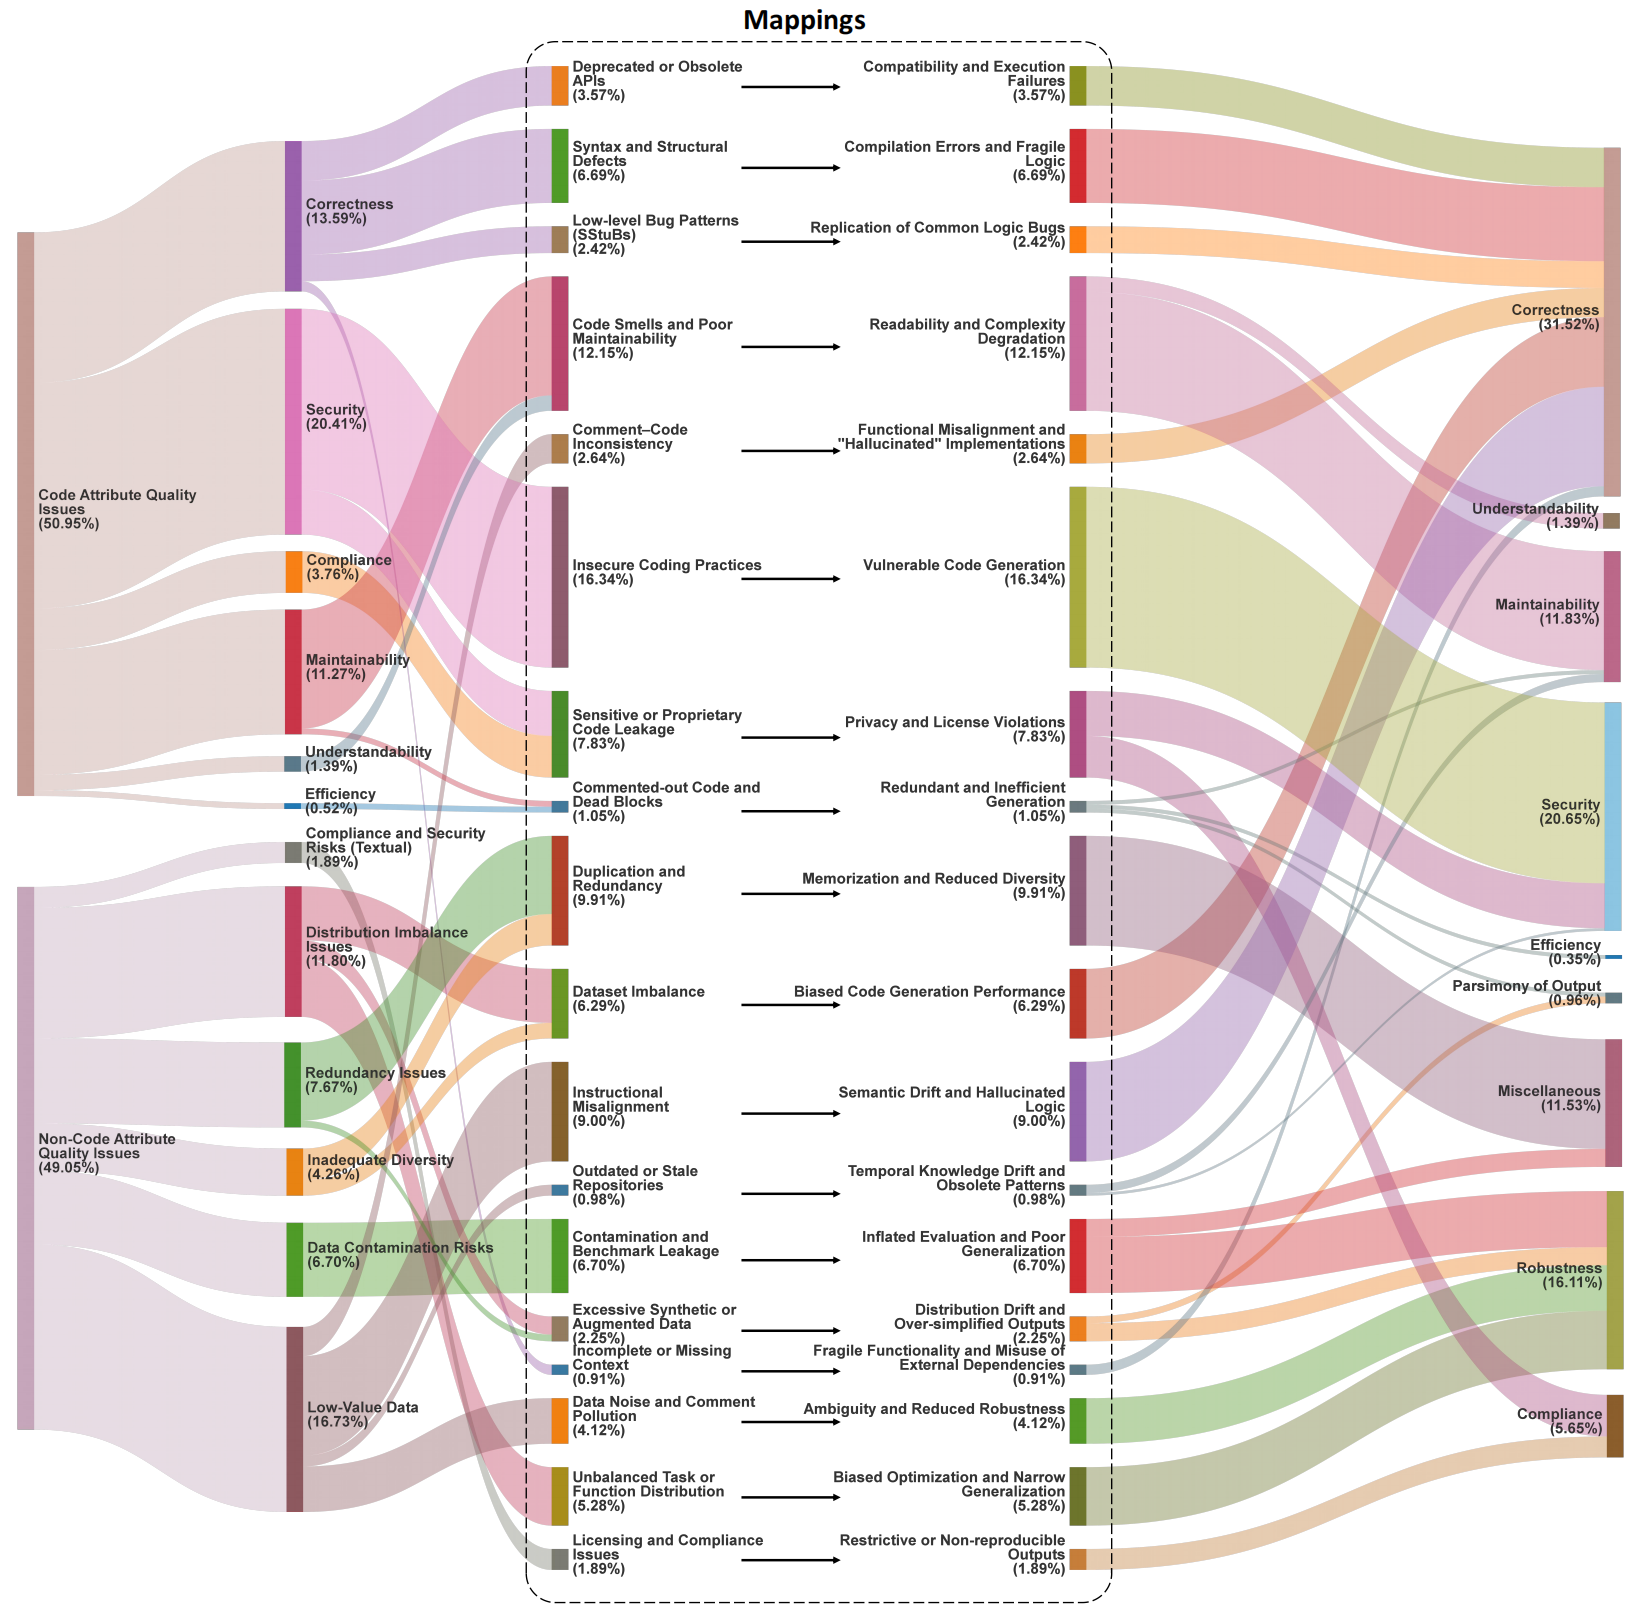
We synthesize 12 recurring relationship families between training-data conditions and observable generated-code outcomes. Evidence includes controlled interventions, corpus audits, output probes, cross-model comparisons, reviews, and authors’ interpretations. Family definitions preserve these differences and their limitations.
Explore the interactive graph · Download the manuscript figure (PDF) · Read the data guide
One assignment is a unique (paper, relationship family, RQ2 source, RQ1 outcome) combination. Repeated passages supporting the same combination count once. A paper can contribute several assignments when the relationships differ. The graph contains 101 assignments from 67 papers , linked to 105 evidence records through 107 normalized evidence links . Width is not an effect-size or causal-strength estimate.
Family Assignments Share Papers F01: Defect-Pattern Carryover 14 13.86% 14 F02: Vulnerability-Pattern Carryover 10 9.90% 10 F03: Restricted/Sensitive-Content Reproduction Risks 8 7.92% 6 F04: Structural-Quality Associations 1 0.99% 1 F05: Clarity-Pattern Associations 2 1.98% 2 F06: Efficiency-Pattern Carryover 4 3.96% 4 F07: Supervision-Signal Quality Associations 12 11.88% 11 F08: Redundancy-Associated Reinforcement and Degeneration 3 2.97% 3 F09: Prevalence-Associated Quality Skew 18 17.82% 17 F10: Underexposure-Associated Quality Gaps 24 23.76% 22 F11: Contamination-Associated Familiarity Differences 3 2.97% 3 F12: Robustness-Pattern Associations 2 1.98% 2
Select a paper count to open that family’s supporting papers. See the operational definitions for routing rules and boundaries, and the assignment table for individual paths. Rounded shares can sum to 99.99%.
Correctness accounts for 61/101 assignments (60.4%) . Underexposure, prevalence skew, defect carryover, and supervision-signal quality together account for 68/101 (67.3%) . These concentrations describe the literature’s attention. Robustness, Maintainability, and Understandability together receive six assignments.
The evidence supports examining example quality, input–target alignment, and coverage against deployment requirements. Interpretation remains study-specific: bundled cleaning may not isolate an individual filter’s effect, hidden corpora limit attribution, and observed associations can have several explanations. The evidence table and path links retain source locations and qualifiers.
Browse 67 distinct papers by relationship family. Each group contains distinct papers, even when a paper contributes several paths within that family. A paper can appear in several families; group counts are not additive. Stable study IDs trace back to the assignment table and its evidence links.
F01 Defect-Pattern Carryover14 papers LLMs Meet Library Evolution
LLMs Meet Library Evolution: Evaluating Deprecated API Usage in LLM-based Code Completion
CodeHalu
CodeHalu: Investigating Code Hallucinations in LLMs via Execution-based Verification
SStuBs
Large Language Models and Simple, Stupid Bugs
package hallucinations
We Have a Package for You! A Comprehensive Analysis of Package Hallucinations by Code Generating LLMs
Bugs in LLM-generated Code
Bugs in Large Language Models Generated Code: An Empirical Stud
Infinite-Instruct
Infinite-Instruct: Synthesizing Scaling Code instruction Data with Bidirectional Synthesis and Static Verification
Quality In, Quality Out
Quality In, Quality Out: Investigating Training Data's Role in AI Code Generation
SwallowCode
Rewriting Pre-Training Data Boosts LLM Performance in Math and Code
Code Pretraining
How Does Code Pretraining Affect Language Model Task Performance?
Synthetic Data Generation
Synthetic Data Generation Using Large Language Models: Advances in Text and Code
Cracks in The Stack
Cracks in The Stack: Hidden Vulnerabilities and Licensing Risks in LLM Pre-Training Datasets
RTL-Breaker
RTL-Breaker: Assessing the Security of LLMs Against Backdoor Attacks on HDL Code Generation
aiXcoder-7B
aiXcoder-7B: A Lightweight and Effective Large Language Model for Code Processing
UCD-Training
Unseen-Codebases-Domain Data Synthesis and Training Based on Code Graphs
F02 Vulnerability-Pattern Carryover10 papers Copilot Security
Is GitHub’s Copilot as Bad as Humans at Introducing Vulnerabilities in Code?
Purple Llama CYBERSECEVAL
Purple Llama CYBERSECEVAL: A Secure Coding Benchmark for Language Models
Lost at C
Lost at C: A User Study on the Security Implications of Large Language Model Code Assistants
AI Assistants Security
Do Users Write More Insecure Code with AI Assistants?
DeVAIC
DeVAIC: A Tool for Security Assessment of AI-generated Code
Codex
Evaluating Large Language Models Trained on Code
Cracks in The Stack
Cracks in The Stack: Hidden Vulnerabilities and Licensing Risks in LLM Pre-Training Datasets
RTL-Breaker
RTL-Breaker: Assessing the Security of LLMs Against Backdoor Attacks on HDL Code Generation
Llm Hallucinations in Practical Code Generation
Llm hallucinations in practical code generation: Phenomena, mechanism, and mitigation
AATK Benchmark
Asleep at the keyboard? assessing the security of github copilot's code contributions
F03 Restricted/Sensitive-Content Reproduction Risks6 papers DeSec
Decoding Secret Memorization in Code LLMs Through Token-Level Characterization
Artificial-Intelligence Generated Code Considered Harmful
Artificial-Intelligence Generated Code Considered Harmful: A Road Map for Secure and High-Quality Code Generation
CodeMI
Does Your Neural Code Completion Model Use My Code? A Membership Inference Approach
Codex
Evaluating Large Language Models Trained on Code
Cracks in The Stack
Cracks in The Stack: Hidden Vulnerabilities and Licensing Risks in LLM Pre-Training Datasets
Code Generation Survey
A Survey on Large Language Models for Code Generation
F04 Structural-Quality Associations1 paper CodeSmellEval
How Propense Are Large Language Models at Producing Code Smells? A Benchmarking Study
F05 Clarity-Pattern Associations2 papers Synthetic Data Generation
Synthetic Data Generation Using Large Language Models: Advances in Text and Code
ShortCoder
ShortCoder: Knowledge-Augmented Syntax Optimization for Token-Efficient Code GenerationPreprint
F06 Efficiency-Pattern Carryover4 papers EffiBench
EffiBench: Benchmarking the Efficiency of Automatically Generated Code
Mercury
Mercury: A Code Efficiency Benchmark for Code Large Language Models
RTL-Breaker
RTL-Breaker: Assessing the Security of LLMs Against Backdoor Attacks on HDL Code Generation
ShortCoder
ShortCoder: Knowledge-Augmented Syntax Optimization for Token-Efficient Code GenerationPreprint
F07 Supervision-Signal Quality Associations11 papers Less is More
Less is More: On the Importance of Data Quality for Unit Test Generation
Large Language Models for Code
Large Language Models for Code: Security Hardening and Adversarial Testing
CIDRe
CIDRe: A Reference-Free Multi-Aspect Criterion for Code Comment Quality Measurement
Data-efficient Fine-tuning
Data-efficient LLM Fine-tuning for Code Generation
CRPE
CRPE: Expanding The Reasoning Capability of Large Language Model for Code Generation
DeepSeek-Coder
DeepSeek-Coder: When the Large Language Model Meets Programming -- The Rise of Code Intelligence
Brevity is the soul of wit
Brevity is the soul of wit: Pruning long files for code generation
Benchmark Builders
Large Language Models are Qualified Benchmark Builders: Rebuilding Pre-Training Datasets for Advancing Code Intelligence Tasks
MG-Verilog
MG-Verilog: Multi-grained Dataset Towards Enhanced LLM-assisted Verilog Generation
Code Generation Survey
A Survey on Large Language Models for Code Generation
DataRecipe
DataRecipe --- How to Cook the Data for CodeLLM?
F08 Redundancy-Associated Reinforcement and Degeneration3 papers CodeHalu
CodeHalu: Investigating Code Hallucinations in LLMs via Execution-based Verification
Data-efficient Fine-tuning
Data-efficient LLM Fine-tuning for Code Generation
Code Copycat Conundrum
Code Copycat Conundrum: Demystifying Repetition in LLM-based Code Generation
F09 Prevalence-Associated Quality Skew17 papers LLMs Meet Library Evolution
LLMs Meet Library Evolution: Evaluating Deprecated API Usage in LLM-based Code Completion
Phi-4
Phi-4 Technical Report
EffiBench
EffiBench: Benchmarking the Efficiency of Automatically Generated Code
CloudAPIBench
On Mitigating Code LLM Hallucinations with API Documentation
AutoAPIEval
A Comprehensive Framework for Evaluating API-oriented Code Generation in Large Language Models
Unveiling Inefficiencies in LLM-Generated Code
Unveiling Inefficiencies in LLM-Generated Code: Toward a Comprehensive Taxonomy
Data-efficient Fine-tuning
Data-efficient LLM Fine-tuning for Code Generation
Code Pretraining
How Does Code Pretraining Affect Language Model Task Performance?
StarCoder 2 and The Stack v2
StarCoder 2 and The Stack v2: The Next Generation
Code Data Training Stage
At Which Training Stage Does Code Data Help LLMs Reasoning?
Beyond Correctness
Beyond Correctness: Benchmarking Multi-dimensional Code Generation for Large Language Models
Codex
Evaluating Large Language Models Trained on Code
Path Planning Evaluation
Assessing LLM code generation quality through path planning tasks
MG-Verilog
MG-Verilog: Multi-grained Dataset Towards Enhanced LLM-assisted Verilog Generation
aiXcoder-7B
aiXcoder-7B: A Lightweight and Effective Large Language Model for Code Processing
APIKG4SYN
Framework-Aware Code Generation with API Knowledge Graph-Constructed Data: A Study on HarmonyOS
AATK Benchmark
Asleep at the keyboard? assessing the security of github copilot's code contributions
F10 Underexposure-Associated Quality Gaps22 papers Qwen
Qwen Technical Report
Qwen2
Qwen2 Technical Report
HalluCode
Exploring and Evaluating Hallucinations in LLM-Powered Code Generation
CodeHalu
CodeHalu: Investigating Code Hallucinations in LLMs via Execution-based Verification
package hallucinations
We Have a Package for You! A Comprehensive Analysis of Package Hallucinations by Code Generating LLMs
HallTrigger
Code Hallucination
ChatGPT Code Quality
No Need to Lift a Finger Anymore? Assessing the Quality of Code Generation by ChatGPT
When Fine-Tuning LLMs Meets Data Privacy
When Fine-Tuning LLMs Meets Data Privacy: An Empirical Study of Federated Learning in LLM-Based Program Repair
DeVAIC
DeVAIC: A Tool for Security Assessment of AI-generated Code
Software Librarian
Is ChatGPT a Good Software Librarian? An Exploratory Study on the Use of ChatGPT for Software Library Recommendations
Infinite-Instruct
Infinite-Instruct: Synthesizing Scaling Code instruction Data with Bidirectional Synthesis and Static Verification
Security and Quality in LLM-Generated Code
Security and Quality in LLM-Generated Code: A Multi-Language, Multi-Model Analysis
ReCode
ReCode: Updating Code API Knowledge with Reinforcement Learning
WaveCoder
WaveCoder: Widespread And Versatile Enhancement For Code Large Language Models By Instruction Tuning
RedStone
RedStone: Curating General, Code, Math, and QA Data for Large Language Models
Code Llama
Code Llama: Open Foundation Models for Code
Code Generation Survey
A Survey on Large Language Models for Code Generation
UCD-Training
Unseen-Codebases-Domain Data Synthesis and Training Based on Code Graphs
APIKG4SYN
Framework-Aware Code Generation with API Knowledge Graph-Constructed Data: A Study on HarmonyOS
MultiCodeIF
A hierarchical and evolvable benchmark for fine-grained code instruction following with multi-turn feedback
RustEvo^ 2
RustEvo^ 2: An Evolving Benchmark for API Evolution in LLM-based Rust Code Generation
Llm Hallucinations in Practical Code Generation
Llm hallucinations in practical code generation: Phenomena, mechanism, and mitigation
F11 Contamination-Associated Familiarity Differences3 papers Beyond Correctness
Beyond Correctness: Benchmarking Multi-dimensional Code Generation for Large Language Models
Unseen Horizons
Unseen Horizons: Unveiling the Real Capability of LLM Code Generation Beyond the Familiar
LLM-ProS
LLM-ProS: Analyzing Large Language Models’ Performance in Competitive Problem Solving
F12 Robustness-Pattern Associations2 papers Less is More
Less is More: On the Importance of Data Quality for Unit Test Generation
Beyond Functional Correctness
Beyond functional correctness: Investigating coding style inconsistencies in large language models