RQ4: Detecting quality issues

Detection depends on the artifact, available oracle, language, and deployment context. Outcomes from heterogeneous evaluations support conditional selection; they do not establish a universal method ranking.

Family Applicable when Operational value Cost and limitation
Execution and resource measurement Code can run with tests, a reference behavior, or a representative workload Reveals behavioral failures, runtime, or memory use Requires dependencies, inputs, and an oracle; finite testing cannot prove equivalence
Static, rule, metadata, and overlap analysis Parsers, rules, API maps, provenance, or comparison sets exist Flags encoded patterns without running the artifact Coverage depends on rules, language support, thresholds, and metadata
General LLM evaluation A rubric and capable contextual evaluator are available Supports qualitative judgment and triage where fixed oracles are absent Sensitive to evaluator, prompt, order, and context; requires calibration and inference cost
Task-specific learned scoring In-domain labels or a learnable proxy exist Enables versioned batch scoring Label construction and training cost; transfer can fail under domain shift
Human or hybrid review Ambiguous findings require contextual judgment Helps construct labels and validate automated flags Expert effort and disagreement limit throughput; most reviewed evidence concerns research annotation

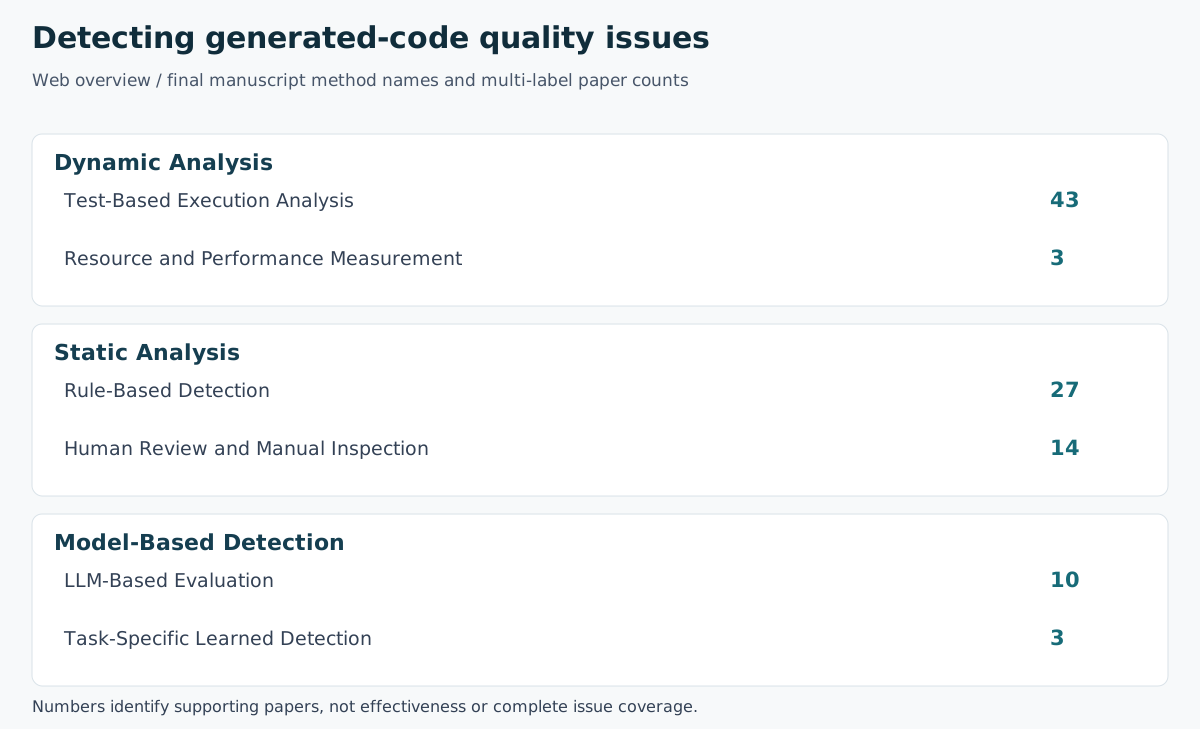
Generated-code detection

Generated-code detection methods. A paper can support several methods. View full-size figure ↗
MethodPath in taxonomyPapers
Test-Based Execution AnalysisDynamic Analysis > Test-Based Execution Analysis43
Resource and Performance MeasurementDynamic Analysis > Resource and Performance Measurement3
Rule-Based DetectionStatic Analysis > Rule-Based Detection27
Human Review and Manual InspectionStatic Analysis > Human Review and Manual Inspection14
LLM-Based EvaluationModel-Based Detection > LLM-Based Evaluation10
Task-Specific Learned DetectionModel-Based Detection > Task-Specific Learned Detection3

Select a paper count to open its supporting papers. Counts are multi-label literature memberships. Download the method definitions and paper–method memberships to trace each entry.

Training-data detection
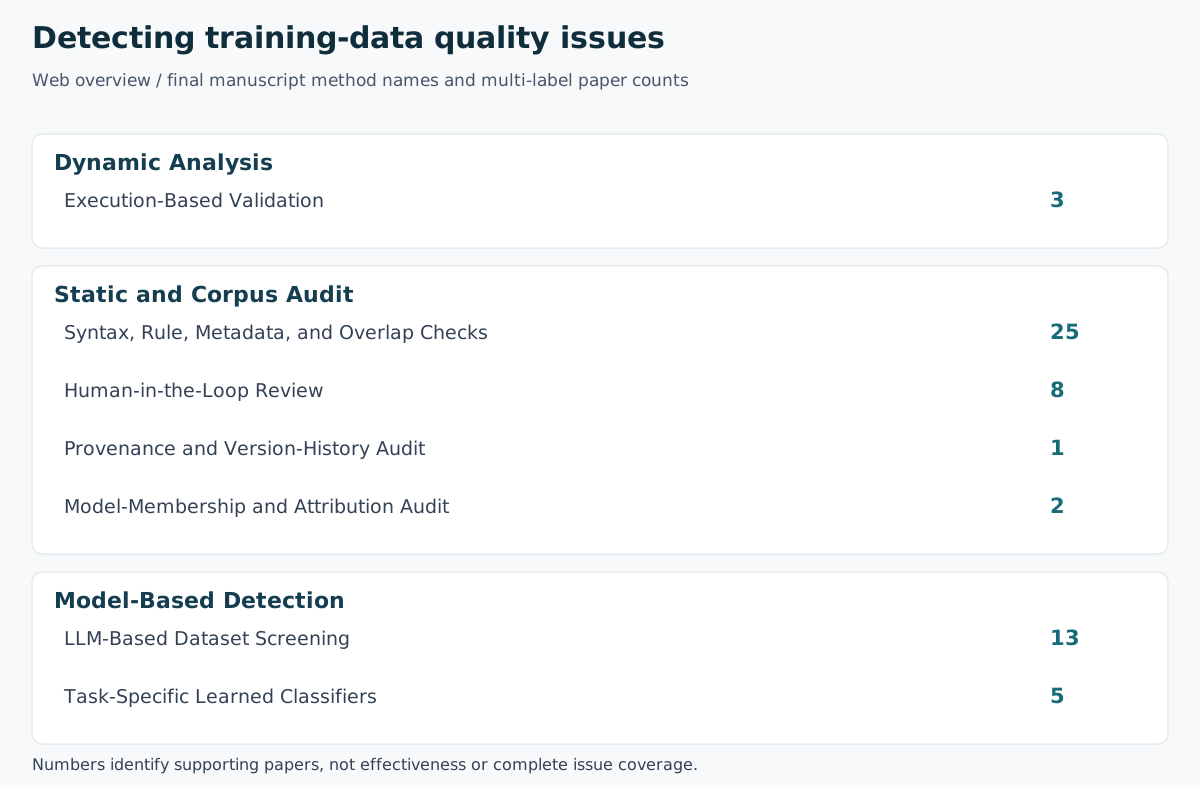
Training-data detection methods. A paper can support several methods. View full-size figure ↗
MethodPath in taxonomyPapers
Execution-Based ValidationDynamic Analysis > Execution-Based Validation3
Syntax, Rule, Metadata, and Overlap ChecksStatic and Corpus Audit > Syntax, Rule, Metadata, and Overlap Checks25
Human-in-the-Loop ReviewStatic and Corpus Audit > Human-in-the-Loop Review8
Provenance and Version-History AuditStatic and Corpus Audit > Provenance and Version-History Audit1
Model-Membership and Attribution AuditStatic and Corpus Audit > Model-Membership and Attribution Audit2
LLM-Based Dataset ScreeningModel-Based Detection > LLM-Based Dataset Screening13
Task-Specific Learned ClassifiersModel-Based Detection > Task-Specific Learned Classifiers5

Select a paper count to open its supporting papers. Counts are multi-label literature memberships. Download the method definitions and paper–method memberships to trace each entry.

Automation evidence and residual gaps

The 21-row automation crosswalk identifies a direct automated detection exemplar and a direct automated mitigation exemplar for each of eight code headings and 13 data headings. They can address different subtypes. The result establishes existence at a broad-heading level; it does not establish complete subtype coverage, paired detection and mitigation, or deployment readiness.

Human work remains in constructing rules, tests, labels, prompts, and thresholds, and in adjudicating context-sensitive findings. Important gaps include output-side copyright and privacy leakage, semantic contamination, repository-scale structural quality, and end-to-end CI/CD evaluation. RQ3 relationship families do not constitute an additional issue-detection denominator.

Supporting papers

Browse 94 distinct papers by detection method, separated by the artifact being checked. Expand a method to see its taxonomy path and supporting papers, or select its paper count in the tables above. Membership is multi-label: a paper can appear under several methods. The paper–method memberships retain the exact assignments.

Generated-code detection

Test-Based Execution Analysis 43 papers

Dynamic Analysis > Test-Based Execution Analysis

Copilot Evaluation
An Empirical Evaluation of GitHub Copilot’s Code Suggestions
S008 · May-22View Paper ↗
CodeHalu
CodeHalu: Investigating Code Hallucinations in LLMs via Execution-based Verification
S010 · May-24View Paper ↗
Mercury
Mercury: A Code Efficiency Benchmark for Code Large Language Models
S012 · Feb-24View Paper ↗
HallTrigger
Code Hallucination
S015 · Jul-24View Paper ↗
Lost at C
Lost at C: A User Study on the Security Implications of Large Language Model Code Assistants
S018 · Aug-22View Paper ↗
The Counterfeit Conundrum
The Counterfeit Conundrum: Can Code Language Models Grasp the Nuances of Their Incorrect Generations?
S020 · Feb-24View Paper ↗
Bugs in LLM-generated Code
Bugs in Large Language Models Generated Code: An Empirical Stud
S021 · Mar-24View Paper ↗
GitHub Copilot, Amazon CodeWhisperer, ChatGPT
Evaluating the Code Quality of AI-Assisted Code Generation Tools: An Empirical Study on GitHub Copilot, Amazon CodeWhisperer, and ChatGPT
S022 · Apr-23View Paper ↗
ChatGPT Code Quality
No Need to Lift a Finger Anymore? Assessing the Quality of Code Generation by ChatGPT
S023 · Aug-23View Paper ↗
LLM-generated Code Efficiency
On Evaluating the Efficiency of Source Code Generated by LLMs
S026 · Apr-24View Paper ↗
Syntactic Robustness
Syntactic Robustness for LLM-based Code Generation
S027 · Apr-24View Paper ↗
Bias Unveiled
Bias Unveiled: Investigating Social Bias in LLM-Generated Code
S032 · Nov-24View Paper ↗
From Effectiveness to Efficiency
From Effectiveness to Efficiency: Comparative Evaluation of Code Generated by LCGMs for Bilingual Programming Questions
S035 · Jun-24View Paper ↗
ENAMEL
How Efficient is LLM-Generated Code? A Rigorous & High-Standard Benchmark
S036 · Jun-24View Paper ↗
PTMs
Comparing Robustness Against Adversarial Attacks in Code Generation: LLM-Generated vs. Human-Written
S038 · Nov-24View Paper ↗
Artificial-Intelligence Generated Code Considered Harmful
Artificial-Intelligence Generated Code Considered Harmful: A Road Map for Secure and High-Quality Code Generation
S041 · Sep-24View Paper ↗
Python Tests Quality
Quality Assessment of Python Tests Generated by Large Language Models
S043 · Jun-25View Paper ↗
REAL
Training Language Models to Generate Quality Code with Program Analysis Feedback
S045 · May-25View Paper ↗
Quality In, Quality Out
Quality In, Quality Out: Investigating Training Data's Role in AI Code Generation
S048 · Mar-25View Paper ↗
Security and Quality in LLM-Generated Code
Security and Quality in LLM-Generated Code: A Multi-Language, Multi-Model Analysis
S049 · Feb-25View Paper ↗
SwallowCode
Rewriting Pre-Training Data Boosts LLM Performance in Math and Code
S050 · May-25View Paper ↗
Refining ChatGPT-Generated Code
Refining ChatGPT-Generated Code: Characterizing and Mitigating Code Quality Issues
S052 · Jul-23View Paper ↗
ReCode
ReCode: Updating Code API Knowledge with Reinforcement Learning
S057 · Jun-25View Paper ↗
Data-efficient Fine-tuning
Data-efficient LLM Fine-tuning for Code Generation
S059 · Apr-25View Paper ↗
CRPE
CRPE: Expanding The Reasoning Capability of Large Language Model for Code Generation
S060 · May-25View Paper ↗
DeepSeek-Coder
DeepSeek-Coder: When the Large Language Model Meets Programming -- The Rise of Code Intelligence
S061 · Jan-24View Paper ↗
Beyond Correctness
Beyond Correctness: Benchmarking Multi-dimensional Code Generation for Large Language Models
S073 · Jul-24View Paper ↗
Codex
Evaluating Large Language Models Trained on Code
S082 · Jul-21View Paper ↗
Path Planning Evaluation
Assessing LLM code generation quality through path planning tasks
S083 · Apr-25View Paper ↗
Synthetic Data Generation
Synthetic Data Generation Using Large Language Models: Advances in Text and Code
S086 · Jan-25View Paper ↗
Unseen Horizons
Unseen Horizons: Unveiling the Real Capability of LLM Code Generation Beyond the Familiar
S088 · Apr-25View Paper ↗
Code Generation Survey
A Survey on Large Language Models for Code Generation
S091 · Aug-24View Paper ↗
DataRecipe
DataRecipe --- How to Cook the Data for CodeLLM?
S092 · Oct-24View Paper ↗
ClassEval
Evaluating Large Language Models in Class-Level Code Generation
S098 · Jun-24View Paper ↗
RealSec-Bench
RealSec-bench: A Benchmark for Evaluating Secure Code Generation in Real-World Repositories
S102 · Jan-26View Paper ↗
ShortCoder
ShortCoder: Knowledge-Augmented Syntax Optimization for Token-Efficient Code GenerationPreprint
S103 · Jan-26View Paper ↗
APIKG4SYN
Framework-Aware Code Generation with API Knowledge Graph-Constructed Data: A Study on HarmonyOS
S104 · Nov-25View Paper ↗
MultiCodeIF
A hierarchical and evolvable benchmark for fine-grained code instruction following with multi-turn feedback
S105 · Jul-25View Paper ↗
Beyond Functional Correctness
Beyond functional correctness: Investigating coding style inconsistencies in large language models
S106 · Jun-24View Paper ↗
Adadec
Adadec: Uncertainty-guided adaptive decoding for llm-based code generation
S107 · Jun-25View Paper ↗
AllianceCoder
What to retrieve for effective retrieval-augmented code generation? an empirical study and beyond
S109 · Mar-25View Paper ↗
RustEvo^ 2
RustEvo^ 2: An Evolving Benchmark for API Evolution in LLM-based Rust Code Generation
S110 · Mar-25View Paper ↗
COFFE
COFFE: A Code Efficiency Benchmark for Code Generation
S113 · Feb-25View Paper ↗
Resource and Performance Measurement 3 papers

Dynamic Analysis > Resource and Performance Measurement

LLM-generated Code Efficiency
On Evaluating the Efficiency of Source Code Generated by LLMs
S026 · Apr-24View Paper ↗
ENAMEL
How Efficient is LLM-Generated Code? A Rigorous & High-Standard Benchmark
S036 · Jun-24View Paper ↗
COFFE
COFFE: A Code Efficiency Benchmark for Code Generation
S113 · Feb-25View Paper ↗
Rule-Based Detection 27 papers

Static Analysis > Rule-Based Detection

LLMs Meet Library Evolution
LLMs Meet Library Evolution: Evaluating Deprecated API Usage in LLM-based Code Completion
S001 · Jun-24View Paper ↗
Copilot Security
Is GitHub’s Copilot as Bad as Humans at Introducing Vulnerabilities in Code?
S007 · Apr-22View Paper ↗
Copilot Evaluation
An Empirical Evaluation of GitHub Copilot’s Code Suggestions
S008 · May-22View Paper ↗
SStuBs
Large Language Models and Simple, Stupid Bugs
S013 · Mar-23View Paper ↗
package hallucinations
We Have a Package for You! A Comprehensive Analysis of Package Hallucinations by Code Generating LLMs
S014 · Jun-24View Paper ↗
HallTrigger
Code Hallucination
S015 · Jul-24View Paper ↗
Large Language Models for Code
Large Language Models for Code: Security Hardening and Adversarial Testing
S016 · Feb-23View Paper ↗
Purple Llama CYBERSECEVAL
Purple Llama CYBERSECEVAL: A Secure Coding Benchmark for Language Models
S017 · Dec-23View Paper ↗
Lost at C
Lost at C: A User Study on the Security Implications of Large Language Model Code Assistants
S018 · Aug-22View Paper ↗
AI Assistants Security
Do Users Write More Insecure Code with AI Assistants?
S019 · Nov-22View Paper ↗
Bugs in LLM-generated Code
Bugs in Large Language Models Generated Code: An Empirical Stud
S021 · Mar-24View Paper ↗
GitHub Copilot, Amazon CodeWhisperer, ChatGPT
Evaluating the Code Quality of AI-Assisted Code Generation Tools: An Empirical Study on GitHub Copilot, Amazon CodeWhisperer, and ChatGPT
S022 · Apr-23View Paper ↗
CloudAPIBench
On Mitigating Code LLM Hallucinations with API Documentation
S024 · Jul-24View Paper ↗
FairCoder
FairCoder: Evaluating Social Bias of LLMs in Code Generation
S033 · Jan-25View Paper ↗
DeVAIC
DeVAIC: A Tool for Security Assessment of AI-generated Code
S037 · Apr-24View Paper ↗
Codequal Analyzer
Improving LLM-Generated Code Quality with GRPO
S040 · Jun-25View Paper ↗
Artificial-Intelligence Generated Code Considered Harmful
Artificial-Intelligence Generated Code Considered Harmful: A Road Map for Secure and High-Quality Code Generation
S041 · Sep-24View Paper ↗
REAL
Training Language Models to Generate Quality Code with Program Analysis Feedback
S045 · May-25View Paper ↗
Quality In, Quality Out
Quality In, Quality Out: Investigating Training Data's Role in AI Code Generation
S048 · Mar-25View Paper ↗
Security and Quality in LLM-Generated Code
Security and Quality in LLM-Generated Code: A Multi-Language, Multi-Model Analysis
S049 · Feb-25View Paper ↗
Refining ChatGPT-Generated Code
Refining ChatGPT-Generated Code: Characterizing and Mitigating Code Quality Issues
S052 · Jul-23View Paper ↗
Seed-Coder
Seed-Coder: Let the Code Model Curate Data for Itself
S058 · Jun-25View Paper ↗
CodeSmellEval
How Propense Are Large Language Models at Producing Code Smells? A Benchmarking Study
S065 · Dec-24View Paper ↗
RPG
Rethinking Repetition Problems of LLMs in Code Generation
S066 · May-25View Paper ↗
Path Planning Evaluation
Assessing LLM code generation quality through path planning tasks
S083 · Apr-25View Paper ↗
MultiCodeIF
A hierarchical and evolvable benchmark for fine-grained code instruction following with multi-turn feedback
S105 · Jul-25View Paper ↗
Code Copycat Conundrum
Code Copycat Conundrum: Demystifying Repetition in LLM-based Code Generation
S108 · Apr-25View Paper ↗
Human Review and Manual Inspection 14 papers

Static Analysis > Human Review and Manual Inspection

Copilot Security
Is GitHub’s Copilot as Bad as Humans at Introducing Vulnerabilities in Code?
S007 · Apr-22View Paper ↗
HalluCode
Exploring and Evaluating Hallucinations in LLM-Powered Code Generation
S009 · Apr-24View Paper ↗
HallTrigger
Code Hallucination
S015 · Jul-24View Paper ↗
Lost at C
Lost at C: A User Study on the Security Implications of Large Language Model Code Assistants
S018 · Aug-22View Paper ↗
AI Assistants Security
Do Users Write More Insecure Code with AI Assistants?
S019 · Nov-22View Paper ↗
The Counterfeit Conundrum
The Counterfeit Conundrum: Can Code Language Models Grasp the Nuances of Their Incorrect Generations?
S020 · Feb-24View Paper ↗
Bugs in LLM-generated Code
Bugs in Large Language Models Generated Code: An Empirical Stud
S021 · Mar-24View Paper ↗
GitHub Copilot, Amazon CodeWhisperer, ChatGPT
Evaluating the Code Quality of AI-Assisted Code Generation Tools: An Empirical Study on GitHub Copilot, Amazon CodeWhisperer, and ChatGPT
S022 · Apr-23View Paper ↗
Syntactic Robustness
Syntactic Robustness for LLM-based Code Generation
S027 · Apr-24View Paper ↗
Security and Quality in LLM-Generated Code
Security and Quality in LLM-Generated Code: A Multi-Language, Multi-Model Analysis
S049 · Feb-25View Paper ↗
Synthetic Data Generation
Synthetic Data Generation Using Large Language Models: Advances in Text and Code
S086 · Jan-25View Paper ↗
Code Generation Survey
A Survey on Large Language Models for Code Generation
S091 · Aug-24View Paper ↗
Beyond Functional Correctness
Beyond functional correctness: Investigating coding style inconsistencies in large language models
S106 · Jun-24View Paper ↗
Llm Hallucinations in Practical Code Generation
Llm hallucinations in practical code generation: Phenomena, mechanism, and mitigation
S112 · Sep-24View Paper ↗
LLM-Based Evaluation 10 papers

Model-Based Detection > LLM-Based Evaluation

The Counterfeit Conundrum
The Counterfeit Conundrum: Can Code Language Models Grasp the Nuances of Their Incorrect Generations?
S020 · Feb-24View Paper ↗
CodeMirage
CodeMirage: Hallucinations in Code Generated by Large Language Models
S025 · Aug-24View Paper ↗
Unveiling Inefficiencies in LLM-Generated Code
Unveiling Inefficiencies in LLM-Generated Code: Toward a Comprehensive Taxonomy
S042 · Mar-25View Paper ↗
CoQuIR
CoQuIR: A Comprehensive Benchmark for Code Quality-Aware Information Retrieval
S044 · Jun-25View Paper ↗
Seed-Coder
Seed-Coder: Let the Code Model Curate Data for Itself
S058 · Jun-25View Paper ↗
Generated Code Diversity
Is Functional Correctness Enough to Evaluate Code Language Models? Exploring Diversity of Generated Codes
S074 · Aug-24View Paper ↗
CODEJUDGE
CODEJUDGE : Evaluating Code Generation with Large Language Models
S084 · Jan-24View Paper ↗
RealSec-Bench
RealSec-bench: A Benchmark for Evaluating Secure Code Generation in Real-World Repositories
S102 · Jan-26View Paper ↗
MultiCodeIF
A hierarchical and evolvable benchmark for fine-grained code instruction following with multi-turn feedback
S105 · Jul-25View Paper ↗
RobGen
A Preliminary Study on the Robustness of Code Generation by Large Language Models
S111 · Mar-25View Paper ↗
Task-Specific Learned Detection 3 papers

Model-Based Detection > Task-Specific Learned Detection

CodeMirage
CodeMirage: Hallucinations in Code Generated by Large Language Models
S025 · Aug-24View Paper ↗
DeSec
Decoding Secret Memorization in Code LLMs Through Token-Level Characterization
S030 · Oct-24View Paper ↗
CIDRe
CIDRe: A Reference-Free Multi-Aspect Criterion for Code Comment Quality Measurement
S046 · May-25View Paper ↗

Training-data detection

Execution-Based Validation 3 papers

Dynamic Analysis > Execution-Based Validation

Qwen2
Qwen2 Technical Report
S004 · Jul-24View Paper ↗
TeleChat
Technical Report of TeleChat2, TeleChat2.5 and T1
S055 · Jul-25View Paper ↗
Kimi K2
Kimi K2: Open Agentic Intelligence
S056 · Jul-25View Paper ↗
Syntax, Rule, Metadata, and Overlap Checks 25 papers

Static and Corpus Audit > Syntax, Rule, Metadata, and Overlap Checks

Less is More
Less is More: On the Importance of Data Quality for Unit Test Generation
S002 · Feb-25View Paper ↗
Qwen
Qwen Technical Report
S003 · Sep-23View Paper ↗
Qwen2
Qwen2 Technical Report
S004 · Jul-24View Paper ↗
Quality In, Quality Out
Quality In, Quality Out: Investigating Training Data's Role in AI Code Generation
S048 · Mar-25View Paper ↗
SwallowCode
Rewriting Pre-Training Data Boosts LLM Performance in Math and Code
S050 · May-25View Paper ↗
TeleChat
Technical Report of TeleChat2, TeleChat2.5 and T1
S055 · Jul-25View Paper ↗
Data-efficient Fine-tuning
Data-efficient LLM Fine-tuning for Code Generation
S059 · Apr-25View Paper ↗
CRPE
CRPE: Expanding The Reasoning Capability of Large Language Model for Code Generation
S060 · May-25View Paper ↗
DeepSeek-Coder
DeepSeek-Coder: When the Large Language Model Meets Programming -- The Rise of Code Intelligence
S061 · Jan-24View Paper ↗
StarCoder 2 and The Stack v2
StarCoder 2 and The Stack v2: The Next Generation
S064 · Feb-24View Paper ↗
Repetition In Repetition Out
Repetition In Repetition Out: Towards Understanding Neural Text Degeneration from the Data Perspective
S067 · Oct-23View Paper ↗
Every Sample Matters
Every Sample Matters: Leveraging Mixture-of-Experts and High-Quality Data for Efficient and Accurate Code LLM
S068 · Mar-25View Paper ↗
WaveCoder
WaveCoder: Widespread And Versatile Enhancement For Code Large Language Models By Instruction Tuning
S070 · Dec-23View Paper ↗
Brevity is the soul of wit
Brevity is the soul of wit: Pruning long files for code generation
S071 · Jul-24View Paper ↗
DataComp-LM
DataComp-LM: In search of the next generation of training sets for language models
S078 · Jun-24View Paper ↗
Codex
Evaluating Large Language Models Trained on Code
S082 · Jul-21View Paper ↗
Datasets for Large Language Models
Datasets for Large Language Models: A Comprehensive Survey
S085 · Feb-24View Paper ↗
Cracks in The Stack
Cracks in The Stack: Hidden Vulnerabilities and Licensing Risks in LLM Pre-Training Datasets
S087 · May-25View Paper ↗
MG-Verilog
MG-Verilog: Multi-grained Dataset Towards Enhanced LLM-assisted Verilog Generation
S090 · Jun-24View Paper ↗
DataRecipe
DataRecipe --- How to Cook the Data for CodeLLM?
S092 · Oct-24View Paper ↗
Training Data Extraction
Understanding Privacy Risks of Large Language Models in Japanese Based on Training Data Extraction Attacks
S093 · Aug-25View Paper ↗
aiXcoder-7B
aiXcoder-7B: A Lightweight and Effective Large Language Model for Code Processing
S094 · Apr-25View Paper ↗
Inter-Dataset Code Duplication
On Inter-Dataset Code Duplication and Data Leakage in Large Language Models
S096 · Jan-25View Paper ↗
LLM-ProS
LLM-ProS: Analyzing Large Language Models’ Performance in Competitive Problem Solving
S097 · May-25View Paper ↗
AATK Benchmark
Asleep at the keyboard? assessing the security of github copilot's code contributions
S114 · Aug-21View Paper ↗
Human-in-the-Loop Review 8 papers

Static and Corpus Audit > Human-in-the-Loop Review

Qwen
Qwen Technical Report
S003 · Sep-23View Paper ↗
DataMan
DataMan: Data Manager for Pre-training Large Language Models
S005 · Feb-25View Paper ↗
TeleChat
Technical Report of TeleChat2, TeleChat2.5 and T1
S055 · Jul-25View Paper ↗
StarCoder 2 and The Stack v2
StarCoder 2 and The Stack v2: The Next Generation
S064 · Feb-24View Paper ↗
Datasets for Large Language Models
Datasets for Large Language Models: A Comprehensive Survey
S085 · Feb-24View Paper ↗
Synthetic Data Generation
Synthetic Data Generation Using Large Language Models: Advances in Text and Code
S086 · Jan-25View Paper ↗
Imperfect Code Generation
Imperfect Code Generation: Uncovering Weaknesses in Automatic Code Generation by Large Language Models
S095 · May-24View Paper ↗
AATK Benchmark
Asleep at the keyboard? assessing the security of github copilot's code contributions
S114 · Aug-21View Paper ↗
Provenance and Version-History Audit 1 paper

Static and Corpus Audit > Provenance and Version-History Audit

Cracks in The Stack
Cracks in The Stack: Hidden Vulnerabilities and Licensing Risks in LLM Pre-Training Datasets
S087 · May-25View Paper ↗
Model-Membership and Attribution Audit 2 papers

Static and Corpus Audit > Model-Membership and Attribution Audit

CodeMI
Does Your Neural Code Completion Model Use My Code? A Membership Inference Approach
S075 · Apr-24View Paper ↗
Uncovering Pretraining Code in LLMs
Uncovering Pretraining Code in LLMs: A Syntax-Aware Attribution Approach
S099 · Nov-25View Paper ↗
LLM-Based Dataset Screening 13 papers

Model-Based Detection > LLM-Based Dataset Screening

Qwen
Qwen Technical Report
S003 · Sep-23View Paper ↗
Qwen2
Qwen2 Technical Report
S004 · Jul-24View Paper ↗
DataMan
DataMan: Data Manager for Pre-training Large Language Models
S005 · Feb-25View Paper ↗
SwallowCode
Rewriting Pre-Training Data Boosts LLM Performance in Math and Code
S050 · May-25View Paper ↗
Qwen3
Qwen3 Technical Report
S053 · May-25View Paper ↗
Qwen2.5
Qwen2.5 Technical Report
S054 · Dec-24View Paper ↗
TeleChat
Technical Report of TeleChat2, TeleChat2.5 and T1
S055 · Jul-25View Paper ↗
Kimi K2
Kimi K2: Open Agentic Intelligence
S056 · Jul-25View Paper ↗
DeepSeek-Coder
DeepSeek-Coder: When the Large Language Model Meets Programming -- The Rise of Code Intelligence
S061 · Jan-24View Paper ↗
WaveCoder
WaveCoder: Widespread And Versatile Enhancement For Code Large Language Models By Instruction Tuning
S070 · Dec-23View Paper ↗
Benchmark Builders
Large Language Models are Qualified Benchmark Builders: Rebuilding Pre-Training Datasets for Advancing Code Intelligence Tasks
S072 · Apr-25View Paper ↗
Datasets for Large Language Models
Datasets for Large Language Models: A Comprehensive Survey
S085 · Feb-24View Paper ↗
DataRecipe
DataRecipe --- How to Cook the Data for CodeLLM?
S092 · Oct-24View Paper ↗
Task-Specific Learned Classifiers 5 papers

Model-Based Detection > Task-Specific Learned Classifiers

Less is More
Less is More: On the Importance of Data Quality for Unit Test Generation
S002 · Feb-25View Paper ↗
DataMan
DataMan: Data Manager for Pre-training Large Language Models
S005 · Feb-25View Paper ↗
Benchmark Builders
Large Language Models are Qualified Benchmark Builders: Rebuilding Pre-Training Datasets for Advancing Code Intelligence Tasks
S072 · Apr-25View Paper ↗
DataComp-LM
DataComp-LM: In search of the next generation of training sets for language models
S078 · Jun-24View Paper ↗
aiXcoder-7B
aiXcoder-7B: A Lightweight and Effective Large Language Model for Code Processing
S094 · Apr-25View Paper ↗

© 2026 SYSUSELab. From Data to Code: Systematic Review of Quality Issues in LLMs for Code.

This site uses Just the Docs, a documentation theme for Jekyll.