Research
本页展示了实验室当前的研究工作,我们的研究方向聚焦于软件工程(SE)与人工智能(AI)交叉领域,主要探索AI4SE(AI赋能软件工程)和SE4AI(软件工程赋能AI)的前沿问题。具体研究包括:基于大模型的智能化开发与维护、软件开发知识图谱、大模型可信评测、可信代码大模型等。致力于利用大规模语言模型(LLM)、知识图谱(KG)等先进AI技术,解决软件工程中的核心挑战,并应对AI应用中的软件工程和系统工程问题。
相关链接请参考:
- GitHub: https://github.com/SYSUSELab/
- Hugging Face: https://huggingface.co/SYSUSELab
Highlighted
[no title info]
[no publisher info]
·
[no date info]
·
[no id info]
All
2026
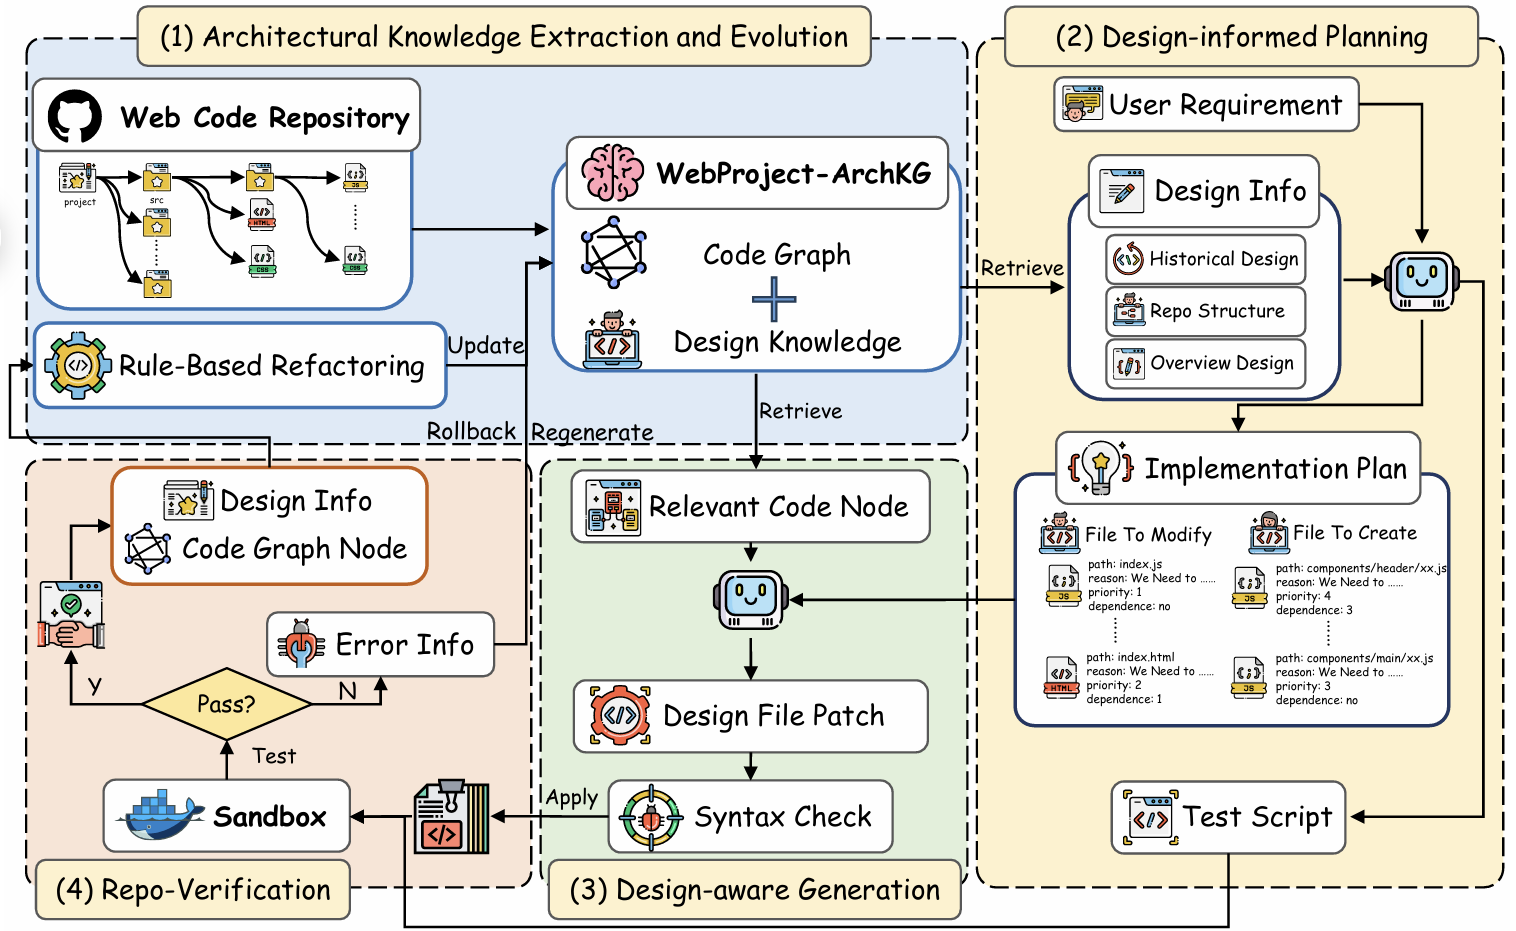
WebDesignIter: Co-Evolving Design Knowledge for Repository-Level Front-End Code Generation
arXiv
·
14 Jul 2026
·
arxiv:2607.10621
本文提出了 WebDesignIter,一种面向仓库级前端代码生成、协同演化设计知识的框架。
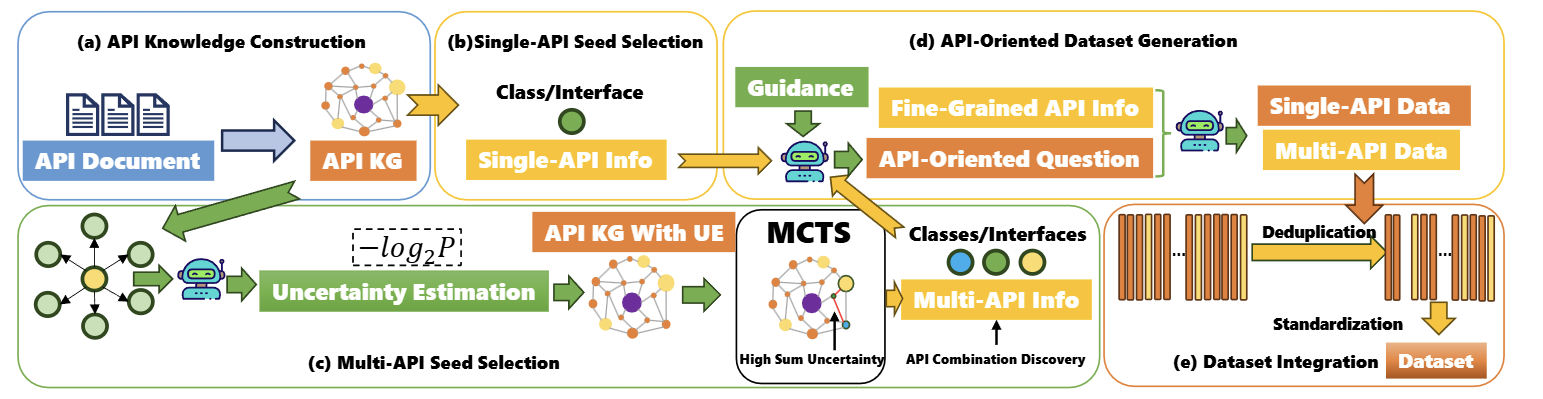
Knowledge-Graph-Driven Data Synthesis for Low-Resource Software Development: A HarmonyOS Case Study
Proc. ACM Softw. Eng. (FSE 2026)
·
30 Jun 2026
·
doi:10.1145/3808133
本文提出了 APIKG4SYN,一种利用 API 知识图谱为 HarmonyOS 等低资源框架合成高质量微调数据的方法。
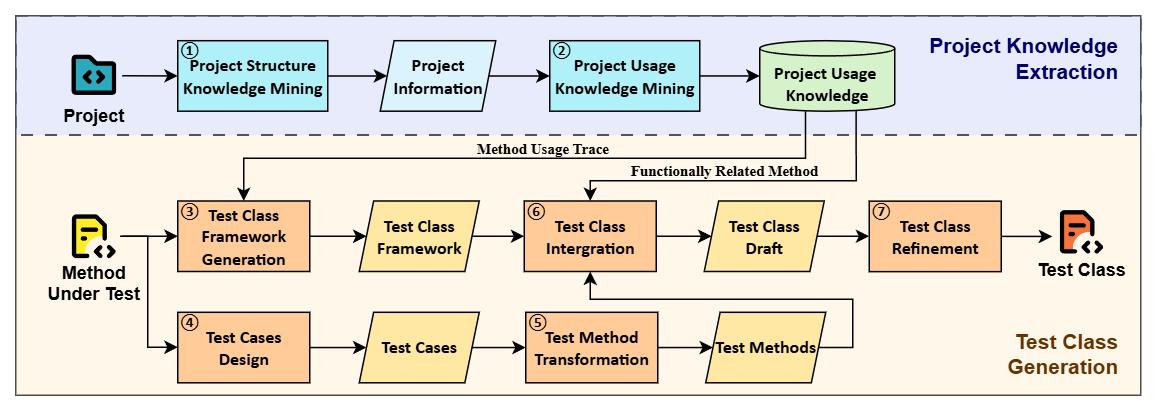
Knowledge Matters: Injecting Project and Testing Knowledge into LLM-based Unit Test Generation
arXiv
·
05 Jun 2026
·
arxiv:2511.14224
本文介绍了 KTester,一种将项目和测试知识注入到基于大语言模型的单元测试生成中的方法。
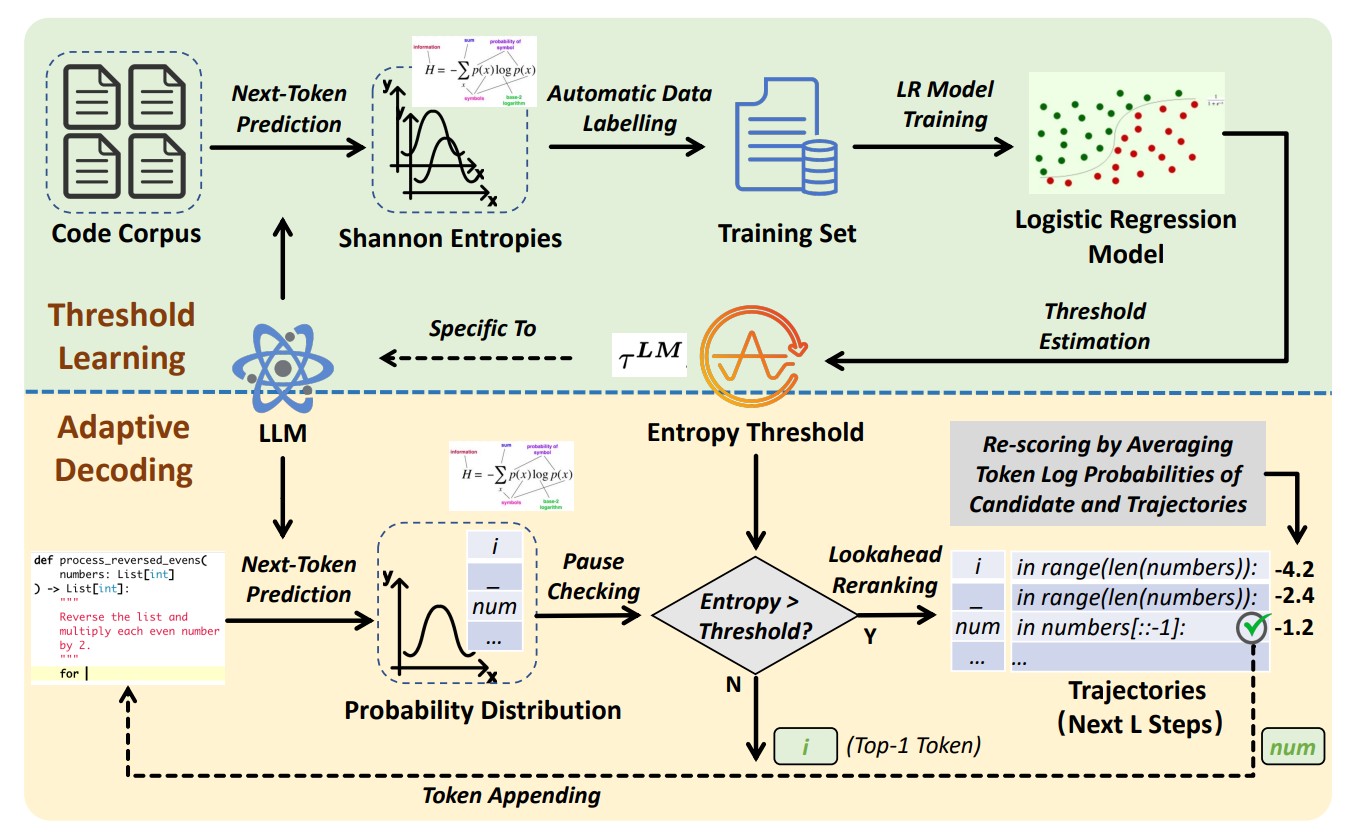
AdaDec: A Uncertainty-Guided Lookahead Decoding Framework for LLM-Based Code Generation
arXiv
·
27 Apr 2026
·
arxiv:2506.08980
本文介绍了 AdaDec,一个用于大型语言模型(LLMs)代码生成的、由不确定性引导的自适应解码框架。
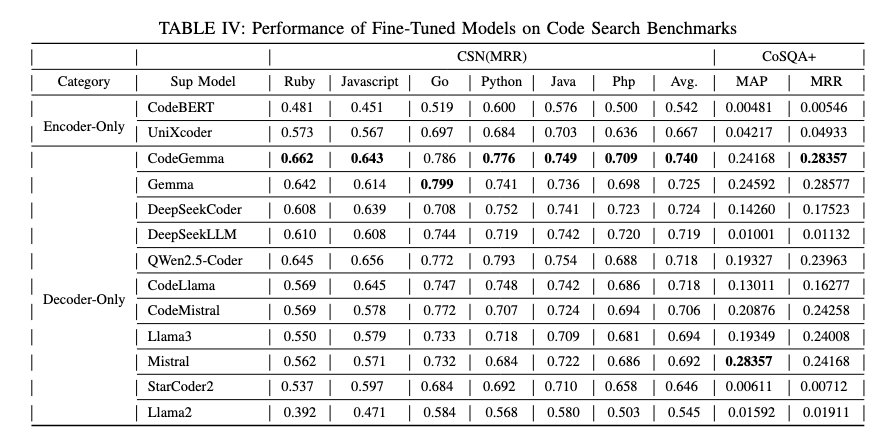
Are Decoder-Only Large Language Models the Silver Bullet for Code Search?
arXiv
·
23 Apr 2026
·
arxiv:2410.22240
本文探讨了仅解码器(Decoder-Only)架构的大语言模型在代码搜索任务中的有效性及其是否为终极解决方案。
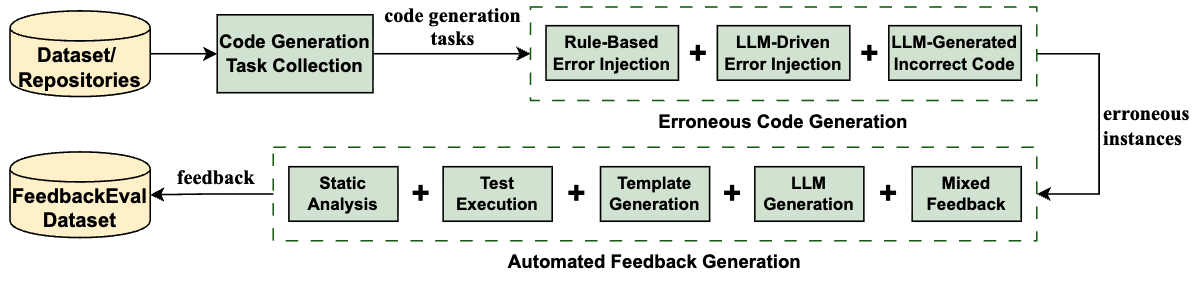
FeedbackEval: A Benchmark for Evaluating Large Language Models in Feedback-Driven Code Repair Tasks
arXiv
·
27 Feb 2026
·
arxiv:2504.06939
本文提出了 FeedbackEval,一个用于在反馈驱动的代码修复场景下评估大型语言模型的基准测试。
2025
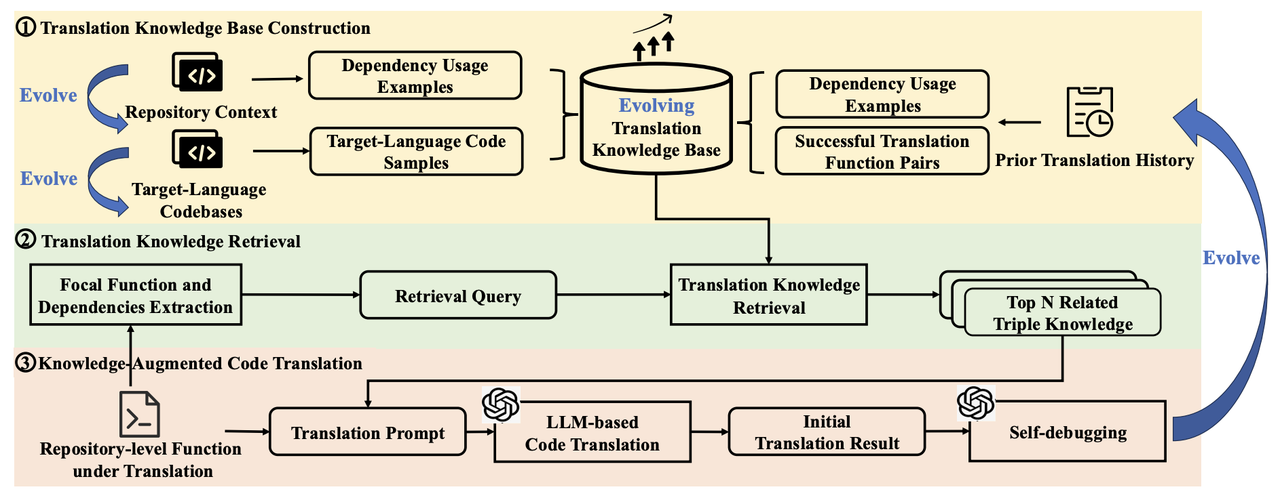
Evolving Triple Knowledge-Augmented LLMs for Code Translation in Repository Context
arXiv
·
25 Nov 2025
·
arxiv:2503.18305
本文提出了 K3Trans 模型,一种利用三重知识增强的大语言模型,用于在代码仓库上下文中进行代码翻译。
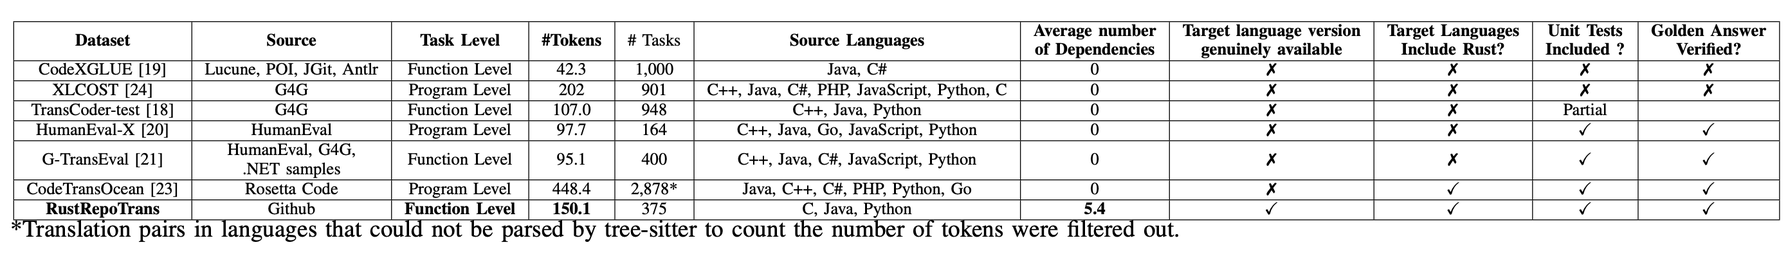
RustRepoTrans: Repository-level Code Translation Benchmark Targeting Rust
arXiv
·
20 Oct 2025
·
arxiv:2411.13990
本文提出了一个针对 Rust 语言的仓库级代码翻译基准测试,关注增量翻译和仓库级上下文。
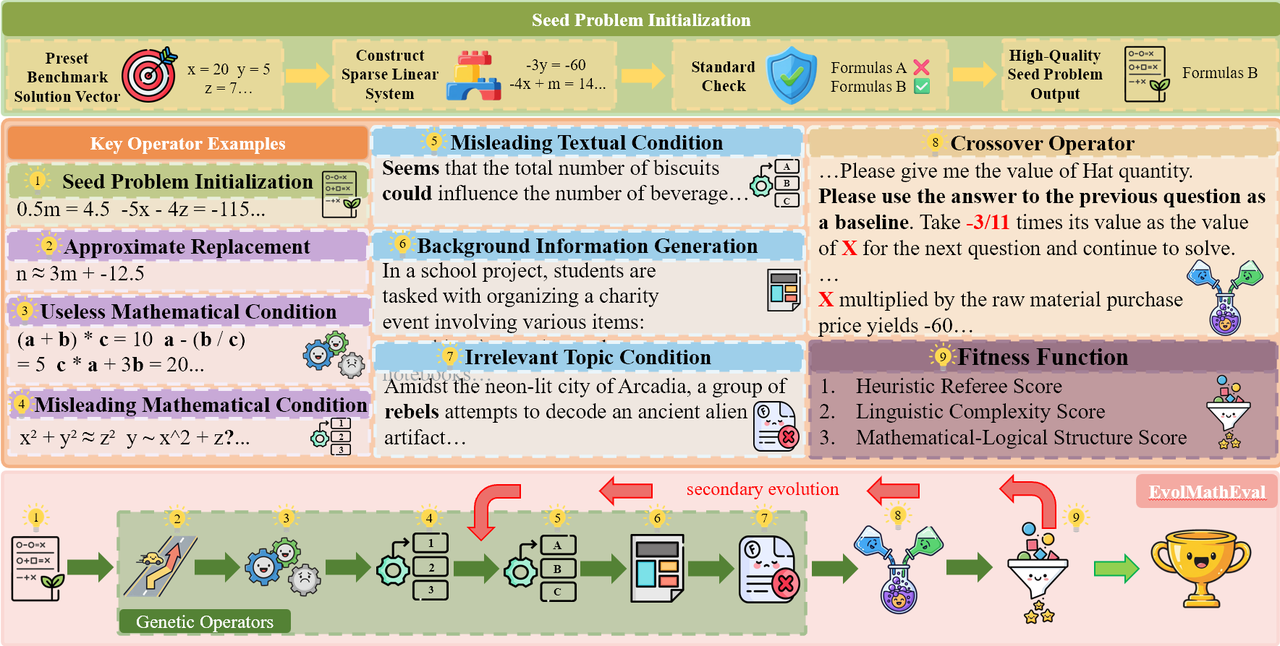
EvolMathEval: Towards Evolvable Benchmarks for Mathematical Reasoning via Evolutionary Testing
arXiv
·
07 Oct 2025
·
arxiv:2508.13003
本文介绍了 EvolMathEval,一个通过演化测试(Evolutionary Testing)为大模型的数学推理能力构建可演化基准测试的方法。